ETL vs ELT looks like a question about three letters in a different order. In practice, it decides where your data gets cleaned, how fast you can add a new report and how much rework a change in business rules will cost. Many teams still run ETL because that is how their first warehouse was built, not because it fits their stack today.
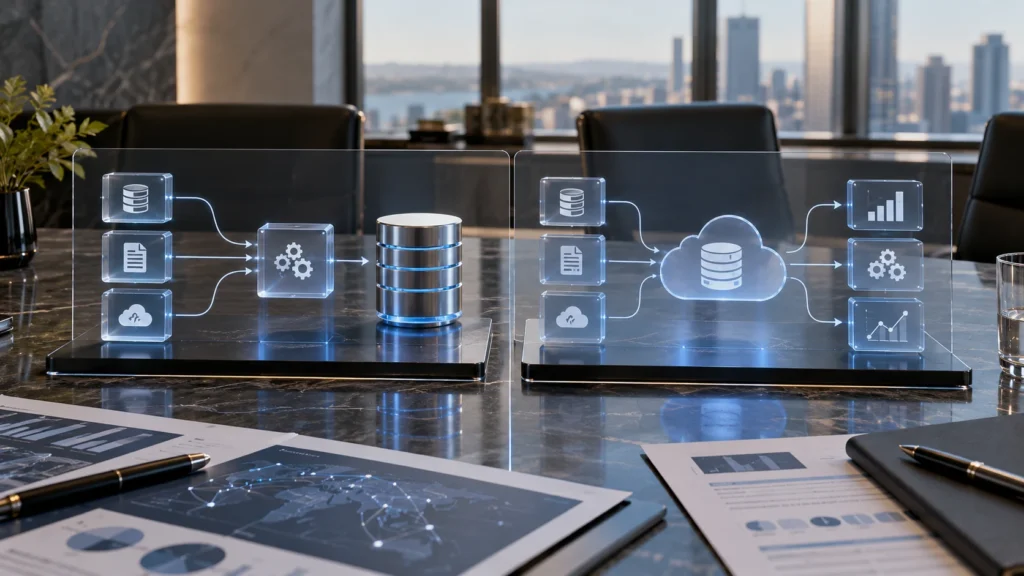
The short answer: ETL transforms data before loading it into the warehouse. ELT loads raw data first and transforms it inside the warehouse. Most modern cloud stacks default to ELT, because cloud warehouses can run heavy transformations at scale. ETL still makes sense when data must be cleaned or masked before it lands. Choosing the pattern is part of every data engineering project we scope.
ETL vs ELT: The Difference in One Table
| ETL | ELT | |
|---|---|---|
| Order | Extract, transform, then load | Extract, load, then transform |
| Where transformation runs | A separate integration server or tool | Inside the cloud warehouse or lakehouse |
| Raw data kept? | Usually not | Yes, in a raw layer |
| Changing a business rule | Rebuild the pipeline and reload | Rewrite the transformation and rerun it on stored raw data |
| Typical setting | On-premises warehouses, legacy integration tools | Snowflake, Databricks, BigQuery, Redshift, Microsoft Fabric |
The key difference is the raw layer. With ELT, the original data stays available, so a new question or a corrected rule doesn’t require going back to the source system.
When ELT Is the Better Fit
- You run a cloud warehouse. Modern cloud platforms are built to transform large volumes with SQL, so a separate transformation server adds cost and another place for things to break.
- Business rules change often. When finance redefines a metric, you rerun the transformation instead of rebuilding the pipeline.
- Several teams need different views. Keeping the raw data lets analytics, finance and data science each model it their own way from the same source.
- You want transformations in version control. SQL transformations stored as code are easier to review, test and roll back.
When ETL Still Makes Sense
- Sensitive data must be masked before it lands. Payroll, health or customer identity data sometimes can’t be stored raw, even in a secure warehouse.
- The destination is limited. Older on-premises warehouses may not have the capacity to transform at scale.
- The volume needs reducing first. High-frequency sensor data is often aggregated before loading, keeping only what analysis needs.
Many stacks end up hybrid: ELT for most sources, with an ETL step for the few that need masking or reduction first.
A Practical Example: Leaving Nightly Packages Behind
Consider a company running an on-premises SQL Server warehouse fed by nightly ETL packages. Every new report needs a package change, and when a load fails, nobody can see the raw data to find out why.
Moving to the cloud, the team lands raw ERP and CRM tables in a raw layer, then builds the reporting models with SQL inside the warehouse. Payroll data still goes through a masking step before it lands. The same raw layer also becomes the staging area for data cleansing before an ERP migration, and the architecture choice itself is covered in data warehouse vs data lake vs lakehouse.
The Bottom Line
ETL vs ELT comes down to where transformation should happen. On a modern cloud platform, ELT is usually the simpler and more flexible default, because raw data stays available and rules are easy to change. Keep ETL for the specific data that must be masked or reduced before it lands.
Sisifo Analytics designs and builds ELT and hybrid pipelines on AWS, Azure and Google Cloud, from the raw layer to the reporting models.
Still running nightly ETL packages that break every month? Book a 30-minute call with our team and we’ll review your pipeline with you.